
The visual synthesis market contains numerous text-to-image engines, yet migrating from laboratory demonstrations to practical creative workflows remains a distinct hurdle. Most models produce compelling results under highly tailored prompts but frequently stumble when handled under everyday production conditions. Having spent extended time directly testing the GPT Image 2 model on Pollo AI, this review provides an unfiltered, objective evaluation of how the architecture behaves across varied asset types, prompt structures, and generation modes.
Rather than approaching this system as a casual novelty, the platform was treated as an active workspace component. The target was to evaluate its spatial control, processing velocity, and structural rendering boundaries. The following observations outline exactly how this advanced engine maps natural language instructions to precise pixel grids.
What Is the GPT Image 2 Model on Pollo AI?
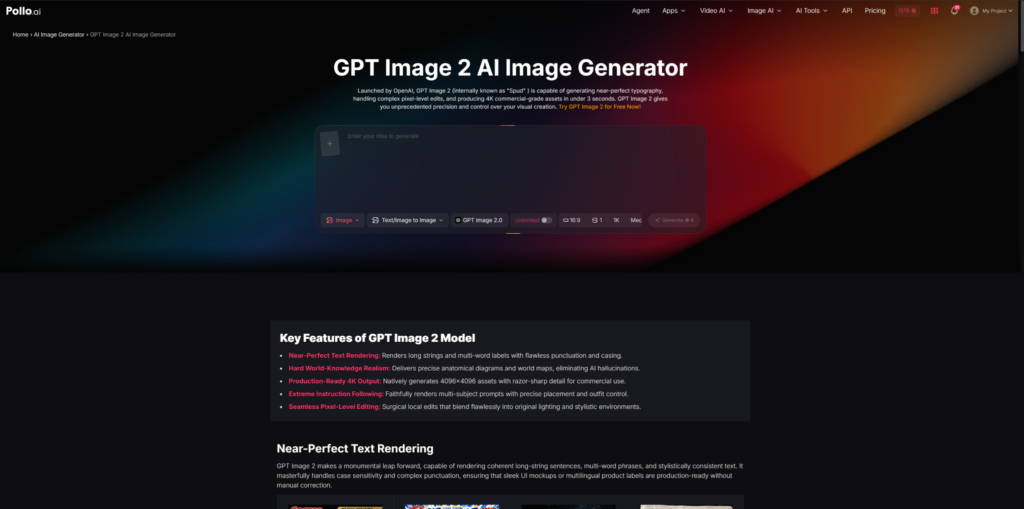
Developed by OpenAI under the internal project designation “Spud,” this engine operates natively as an integrated core framework within the Pollo AI image generator platform. Unlike traditional diffusion setups that process text strings and pixel arrays through separate, disjointed computational steps, this architecture relies on a unified autoregressive multimodal structure. It decodes written commands and designs pixel layouts simultaneously, giving creators substantial precision and control over their visual creation process.
Utilizing the GPT Image 2 model on Pollo AI is straightforward because the interface removes the traditional friction of complex prompt engineering formulas. The dashboard operates on high-performance remote cloud clusters, letting production teams type in their ideas to generate static graphics and instantly port those files into an advanced video timeline (such as Pollo 2.5 or Seedance 2.0). Users looking to evaluate the tool can access the system to try GPT Image 2 for free now, testing its operational limits inside a standard web browser.
Key Features of GPT Image 2 Model on Pollo AI

Testing this autoregressive framework reveals several foundational capabilities that set it apart from legacy diffusion systems, establishing that this model can be easily deployed through Pollo AI to function independently as a standalone AI image generator that introduces an unprecedented level of mechanical accuracy to the creative workspace:
Surgical Pixel-Level Editing
The architecture effectively eliminates the persistent industry problem of “style drift” when revising an existing graphic. When an artist delivers localized conversational modifications—such as adding a steaming cup of coffee to an empty side table or changing a cushion’s texture—the engine limits its calculations strictly to the target coordinates, seamlessly blending the adjustment into the original lighting grid, shadows, and environment without warping the rest of the canvas.
Print-Ready 4K Resolution
Specifically engineered to handle the rigorous demands of large-scale commercial publishing and high-end digital media, the system natively renders massive 4096×4096 pixel layouts. It supports versatile aspect choices up to a 3:1 ratio and outputs file distributions that meet strict CMYK reproduction standards, retaining razor-sharp edge contrast suitable for massive outdoor billboards.
Uncompromising Instruction Adherence
The prompt-parsing core excels at breaking down multi-paragraph, high-density instructions into clear visual hierarchies. Designers can control precise color hex placements, lock down distinct visual positioning, and manage individual clothing elements or traits for multiple separate subjects inside a single complex scene without pixel bleeding.
Flawless Typographic Rendering
The engine makes a monumental leap forward by resolving the traditional failure of AI text generation. It processes long-string sentences, multi-word phrases, and layout labels with correct casing and precise punctuation, making UI mockups, e-commerce packaging, or movie posters production-ready straight out of the generator.
Fact-Driven Visual Realism
Backed by an extensive, built-in repository of world knowledge, the model drastically reduces the frequency of standard AI hallucinations. It relies on strict physical logic and material behaviors, allowing it to correctly construct intricate medical anatomy sketches, complex textbook graphics, and authentic non-famous geographical world maps on the first generation pass.
Workflow Experience and Performance across Image Types
During standardized testing, the GPT Image 2 model delivered impressive rendering speeds, consistently producing 4K commercial-grade assets in under 3 seconds. This rapid generation cycle alters live prototyping, enabling teams to run real-time split-tests on complex prompts during brainstorming sessions. However, the true measure of its capability lies in how it performs across distinct visual mediums and generation modalities.
Performance in Graphic Design and Typographic Layouts
When testing commercial posters, e-commerce layouts, and signage, the engine demonstrates exceptional text control. In rendering a Costco-style discount ad or a detailed supermarket poster, it spells complex phrases like ‘Midnight Noodle Bar’ or ‘The Paper Architect’ perfectly without a single typo. The typography maintains sharp serif or sans-serif definitions on bookstore windows and menus, calculating accurate lighting reflections on text surfaces. While the font choices can occasionally feel somewhat rigid or overly corporate, the lack of lettering warp makes the outputs immediately usable for digital mockups.
Performance in Photographic Realism and Human Portraits
Evaluating human subjects revealed high stability in facial proportions, hand positioning, and physical alignment. In rendering close-up portraits of an elderly woman laughing or a boardroom executive showing subtle exhaustion, the engine preserves genuine skin pores, wrinkles, and fine hairs. It completely sidesteps the flat, overly smooth plastic look common to older synthesizers. Furthermore, environmental illumination wraps around subjects naturally, ensuring that the background blur (bokeh effect) mimics a true high-end camera lens rather than an artificial gradient filter.
Performance in Editorial Illustrations and Academic Diagrams
Testing the system with scientific data, medical anatomy sketches, and textbook illustrations proved its deep common-sense data mapping. It accurately places organs in anatomical drawings and maps out geographical coastlines correctly on world maps. For stylized editorial illustrations, such as a minimalist industrial background or a retro cyberpunk landscape, the composition groups overlapping concepts with high structural clarity, preventing different objects from accidentally blending into one another.
Behavioral Variations across Generation Modes
The system exhibits distinct operational profiles depending on whether the user is executing a brand-new concept or performing a local iteration.
| Operational Phase | Generation Mode | Key Performance Metrics & Structural Output |
| 01. Core Input Integration | Autoregressive Processing Layer | Unified multimodal parsing matrix that analyzes linguistic strings and visual data streams simultaneously instead of using disjointed steps. |
| 02. Initial Synthesis | Text-to-Image Generation | • Under 3-Second 4K Renders: Delivers massive 4096×4096 assets instantly using cloud parallel computing arrays.• Strict Visual Hierarchy: Faithfully maps complex, multi-subject instructions with accurate layout placement.• CMYK Print-Ready Files: Produces razor-sharp clarity optimized for large commercial billboards and digital publishing. |
| 03. Iterative Refinement | Image-to-Image Editing | • Conversational Element Swapping: Modifies, adds, or removes specific objects via simple text-based follow-up commands.• Surgical Shadow & Light Mapping: Blends localized alterations perfectly into the existing atmospheric illumination.• Zero Style Drift: Locks down the surrounding environment to prevent unintended background distortion. |
Text-to-Image Generation Performance
In pure text-to-image mode, the engine treats the written prompt as an absolute visual blueprint. When provided with dense, multi-paragraph descriptions—such as a floating headphone tech poster combining hero shots with macro detail close-ups of metallic mesh fabrics—it honors the exact color hex codes and spatial arrangements requested. It focuses heavily on objective physical logic, resulting in grounded, highly realistic visual hierarchies that favor professional utility over chaotic, abstract fantasy art.
Image-to-Image and Pixel-Level Editing Performance
When switching to conversational editing mode, the platform demonstrates industry-leading environmental continuity. Instructing the model to “change the blue silk pillow on the left side of the sofa to a burnt orange velvet pillow” results in a surgical swap that leaves the surrounding rug texture, lighting, and shadow weights entirely untouched. It handles major changes—like swapping a modern glass table for a dark oak rustic wood table, or changing a character’s iris color from brown to emerald green—without inducing style drift, maintaining the precise reflection maps of the original input file.
Practical Use Cases
The instruction adherence and swift rendering cycles of the GPT Image 2 model make it an exceptionally versatile tool engineered to serve several major creative paths:
- Marketing & Advertising Professionals: Generating social media graphics, product packaging mockups, and promotional banner sets with accurate text and branding.
- UI/UX Designers & Product Managers: Rapidly prototyping app wirefaces, landing page layouts, and modern fashion e-commerce web interfaces with masonry typography.
- Content Creators & Publishers: Outputting detailed infographics, visual reports, tv series posters, livestreams, and book covers with clear data labels.
- E-commerce Businesses: Creating main product photos,packaging layouts, and detail pages containing multi-language instructions directly.
- Educators & Researchers: Constructing precise historical reconstructions, scientific diagrams, or educational materials with clear annotations.
- Game Developers: Concepting character art sheets, UI element sets, and environmental layouts for fast design verification.
Is it Worth it?
From a production and workflow optimization perspective, utilizing the GPT Image 2 model on Pollo AI is a highly valuable choice for commercial enterprises. It effectively solves the persistent visual limitations that have traditionally restricted AI image adoption in professional design—specifically by delivering near-perfect typography, conversational pixel manipulation, and instant 4K print-ready rendering. Production teams can significantly reduce the billable hours typically required to manually correct spelling errors or rebuild distorted assets in external editing programs.
By pairing this advanced engine with Pollo AI’s extensive post-production features, companies can streamline their asset pipelines for free while preserving complete creative control. For any marketing division, design agency, or e-commerce operator aiming to expand content volume without sacrificing typographical or physical precision, the GPT Image 2 model represents an indispensable and highly dependable production asset.